Ground the recommendation in retrieved policy
Understand how RAG retrieves refund policy and distinguish its evidence from the fixed learning response of the order tool.
Question for this chapter
Which policy evidence should be found before the AI recommends a refund decision?
Understand RAG in this situation
RAG prevents the model from relying only on memory. It retrieves relevant passages from refund_policy
and places them in the response context. A high-value laptop request may need the 30-day window, the
over-$500 escalation rule, and the high-value electronics condition together.
Try it
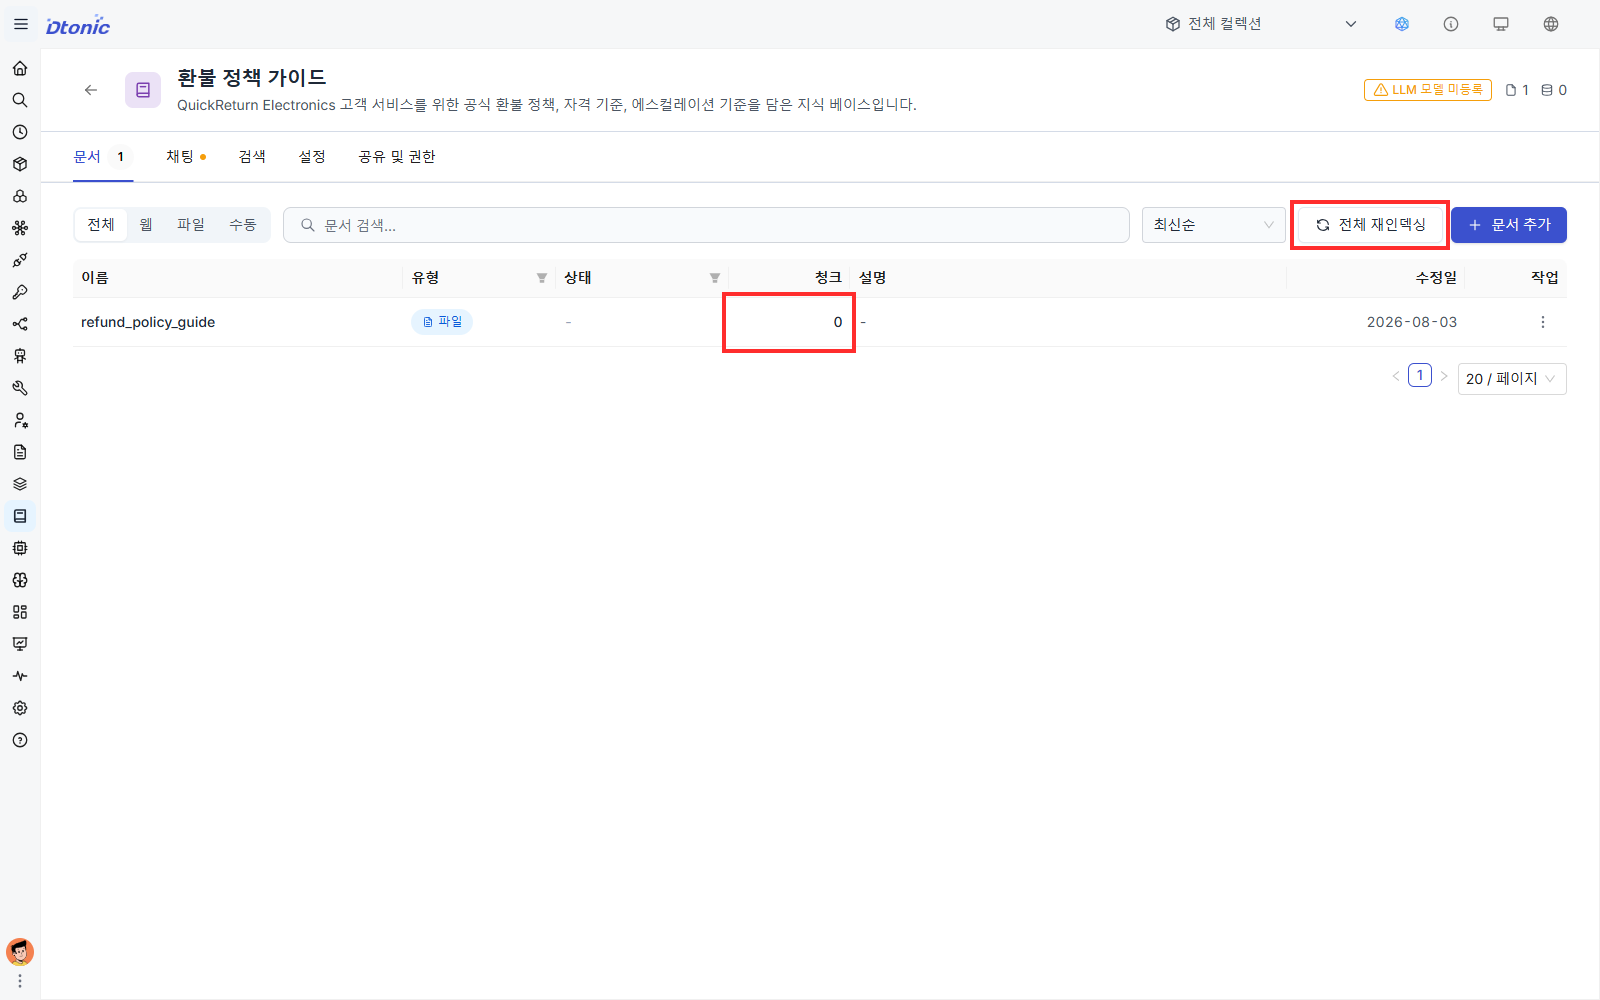
First, select Knowledge → Refund Policy Guide in the left sidebar. In the Documents tab,
inspect the refund_policy_guide row. A chunk count of 9 means policy retrieval is ready.
If the chunk count is 0, select Reindex All → Reindex. The “Reindexing started” notification means the job was accepted. Wait for the status to become Completed and for the chunk count to reach 9. If Completed appears first, wait briefly, refresh the page, and check the chunk count again.
If model credentials are configured, start a new session with the refund-approval Agent and enter a
clearly labeled learning request:
Review a refund for order ORD-DEMO-007.
The reason is defective and the requested amount is $650.
The Agent uses two tools:
get_enriched_order— returns order, customer, and risk contextsearch_refund_policy— retrieves policy passages for the reason and amount with RAG
Policy evidence can contain both auto-approval and escalation rules. A request over $500 meets a current human-review condition.
Confirm the fixed learning response
Next decision
You have order context and policy evidence for an AI recommendation. Next, confirm that no downstream Actor runs before a person approves the decision.